
India proposes a framework for sharing protected data to train AI models
The IT ministry's draft DEPA for AI Training would let startups and researchers build models on data held by banks and hospitals without ever seeing the raw records.
The Global Sun Desk ·
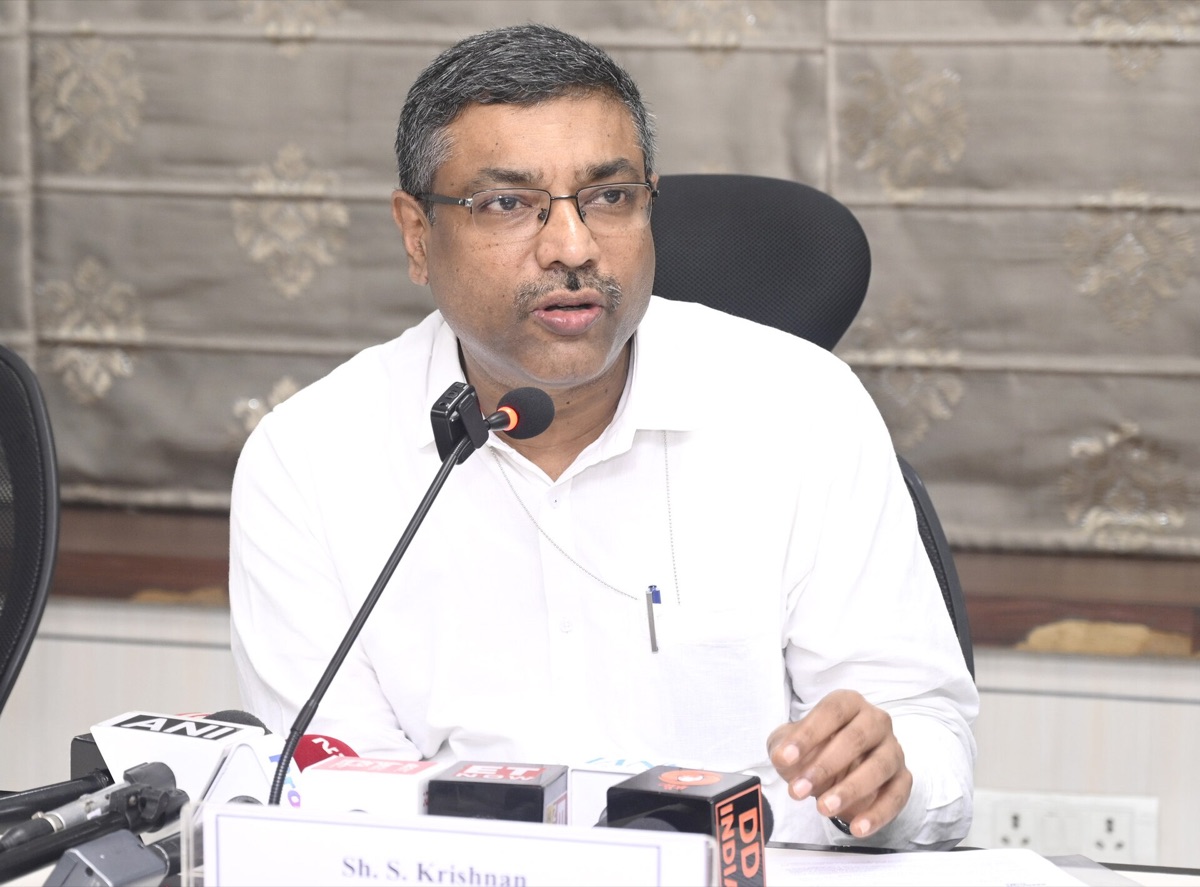
India's Ministry of Electronics and Information Technology (MeitY) has put forward a national framework under which startups, researchers and firms could build AI models using data that currently sits inside hospitals, banks and public agencies. MeitY Secretary S Krishnan unveiled the DEPA for AI Training Handbook on Friday, 30 October, at a roundtable in Bengaluru.
DEPA stands for Data Empowerment and Protection Architecture. The draft was developed jointly with iSPIRT, a technology think tank, and is meant to operate within the Digital Personal Data Protection Act. Its authors describe it as India's digital public infrastructure for AI.
The "data deadlock"
The handbook argues that India is data rich but that the information needed to solve large problems sits behind separate institutional and regulatory walls. It names four obstacles: privacy exposure, risks to institutions and their businesses, the absence of trusted and workable frameworks, and a cost-benefit balance that usually discourages sharing. Stripping out names and ID numbers does not go far enough, it says, because individuals can still be re-identified.
How it would work
The design has four building blocks: an exchange platform for datasets, machine-readable electronic contracts, a secure environment for computation, and differential privacy, a method that stops individuals being picked out of combined data. Organisations that hold data, such as banks, hospitals and government bodies, would register their datasets. Startups, researchers and enterprises would then request access for a specific use, and an electronic contract would check the request against data-sharing rules.
Model training would take place inside the secure environment, so the raw data stays out of the developer's hands. Intermediaries called Data Collabs would pool and standardise data from several sources. Trained models would face checks for bias, security and explainability before deployment, and monitoring would continue afterwards. The government authority named in the framework would certify models, and could halt or withdraw any activity found to break the rules. A consortium drawn from data providers, users, technology firms, subject experts and civil society would oversee the system.
The framework is separate from DEPA Inference, which handles consented sharing of individual data through the Account Aggregator system in finance. DEPA Training, by contrast, deals with large volumes of de-identified data used at the stage when models are first built.
The case being made
The handbook says the framework "provides the potential to unlock $500 billion in AI-driven value for India's GDP by 2030". It values financial services at $550 billion and says DEPA could bring formal credit within reach of 400 million underserved people and small businesses. It also cites a healthcare market of more than $600 billion and an education sector with 250 million students. As evidence that the approach can work, it points to a project by Penn Medicine and Intel across 71 institutions, in which the shared model reached more than 99 per cent of the accuracy of one trained on centralised data.
The first step would be pilot projects in finance and healthcare, alongside regulatory sandboxes. Later phases would bring agreements with other countries, capacity building and incentives such as royalty or access-fee models.
A busy policy week
Inc42 noted that the handbook arrived soon after the telecom regulator TRAI released draft guidelines on responsible AI use in telecom networks, with comments invited by 27 November. It also recalled that IT Minister Ashwini Vaishnaw had said a consultation paper on AI safety and security regulation would follow within a month.